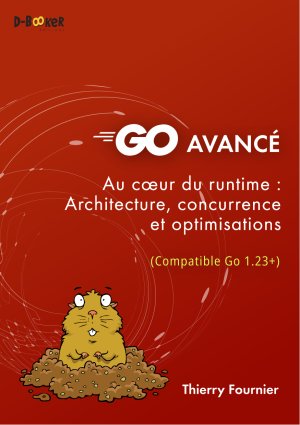
A tour of Go's engine (slices, maps, panics, memory): a good map, with a few errors to check before you follow it.
Why this book
A Go program runs fine, then its container gets killed for lack of memory. A container is the isolated box where the program runs, on a machine shared with others (with Docker, for example). CPU and memory ceilings are set on it. Or changing one list changes another, for no obvious reason. To understand, you have to look under the hood, into Go's runtime: the code embedded in every program, which manages memory and runs tasks in parallel.
That look under the hood is the point of Thierry Fournier's book (D-BookeR publishing). It runs to more than 600 pages on memory, slices, maps, defer and goroutines. It also covers how work is shared between cores, synchronization, the compiler and profiling. The copy, a PDF, was provided to me by Éditions D-BookeR, who offered it after discovering this blog. This note contains no affiliate link, and the review stays frank. The book is in French, so every quotation below is my translation.
This book explains very well what Go does under the hood. But it sometimes gets the detail wrong. A piece of code you could copy does not compile. A "493 times faster" rests on an empty loop: the compiler had removed the allocation you thought you were measuring. I show a few more below, with what you need to check them.
The ideas that stay
The twenty ideas follow the four parts of the book, in its order:
- Runtime foundations (ideas 1 to 7): CPU in a container, startup order, the visibility of a write between goroutines. Then memory: the real cost of an object, the allocator's three tiers, how the garbage collector marks, then its settings.
- Types and data structures (ideas 8 to 12): how a struct is laid out, then what sits behind four everyday types: slice, string, map and interface.
- Advanced language mechanisms (ideas 13 to 16): closures, how a program stops, with or without cleanup, and iterators.
- Mastered concurrency (ideas 17 to 19): the processor cache, the real cost of channels and locks, simulated time in tests.
- Idea 20 sorts the book's errors, last.
1Container limited to one core: Go may run eight threads, Go 1.25 fixes this under one condition
Let's start with the processor. A Go program often has far more goroutines, lightweight tasks started with go, than cores. Go's scheduler runs them in turn on threads, which the system hands to the cores. GOMAXPROCS sets how many threads run Go code at the same time. A running goroutine occupies a thread, placed on a core: it is therefore also the number of goroutines truly running in parallel. By default, it is the number of logical cores Go detects at startup (hyperthreading counts two per physical core, p. 13).
Picture a kitchen. The goroutines are orders to prepare, the threads are the cooks, and GOMAXPROCS is the number of workstations. A cook without a workstation does not cook. The book gives the real names: G for the goroutine, M for the thread, P for the workstation, and each P holds the list of Gs to run (p. 12). Its rule: "no matter how many goroutines are created or threads available, only the number of Ps determines how many goroutines can actually run at the same time" (my translation, p. 13).
Imagine a machine with eight cores, so able to do eight things at once. A container is a box that isolates a program on the machine and imposes limits on it. Here, the box lends you only one core out of eight. How does Linux enforce that limit? With an allowance of computing time, renewed every 100 milliseconds. Each 100 ms period is called a slice.
The allowance is the number of cores lent times 100 ms. One core lent gives 100 ms per slice, two cores give 200 ms, and so on. Think of a tank refilled at the start of each slice: each thread at work draws 1 ms from it per millisecond that passes. When the tank is empty, Linux pauses all the threads until the next slice. This allowance is called a quota, and the Linux mechanism that counts it, a cgroup (p. 19).
The trap, with a Go older than 1.25: Go does not see this allowance. It looks at the machine, counts its eight cores and starts eight threads in parallel. Its GOMAXPROCS is 8 (p. 19).
The book predates Go 1.25 here. The book writes "The Go runtime is not natively aware of cgroup quotas" (my translation, p. 19). That is true up to Go 1.24.
Take one core lent again, so 100 ms of allowance per slice. Eight threads computing without a pause, as in a saturated program, draw 8 ms per millisecond. The tank is therefore empty after 12.5 ms (100 ÷ 8). For the 87.5 ms that remain in the slice, everything is frozen: this is throttling (p. 20).
A request received during this freeze waits for it to end. Hence this sentence: "A request that should take 10ms can then take up to 100ms because of this forced wait" (my translation, p. 20).
The general rule: the tank empties after allowance ÷ number of threads, and the freeze lasts for the rest of the slice. Here is a 100 ms slice, for a container and a program that you set yourself, with threads working without pause. Under the curve, the program runs. Above it, it is frozen. Change the cores lent and GOMAXPROCS:
With 8 threads and 1 core lent, the 100 ms allowance is empty after 12.5 ms, then the freeze lasts 87.5 ms.
Why not go down to 1, which never freezes? Because "Reducing GOMAXPROCS to 1 can negatively affect the garbage collector" (my translation, p. 18). The garbage collector (GC) is the background job that frees the memory of objects no longer used. It usually runs alongside the program, on another thread. With a single thread, they must take turns: the program stops while the GC runs (p. 20). The book therefore sets a floor of 2.
Outside the book, Go 1.25 release notes. Since Go 1.25, Go reads the container quota itself, but only if the go line of go.mod says 1.25 or later. My test, with Docker, --cpus=2 (a quota of 2 cores) and a host, the physical machine, with 16 cores:
go 1.24line: the program sees 16 coresgo 1.25line or later: it sees 2go 1.24line withGODEBUG=containermaxprocs=1: 2
GODEBUG is an environment variable that turns a runtime behavior on or off, and containermaxprocs is this one. With a smaller quota (0.5, 1 or 1.5 cores), Go still sees 2: that is the floor. The book does not mention this change.
The book's remedies still hold for an older Go. The first: read the quota in the cgroup files, then set GOMAXPROCS yourself, through the environment variable of the same name or through runtime.GOMAXPROCS(n) (pp. 14, 20). It gives a formula, GOMAXPROCS = max(2, ceil(quota)): a quota of 200000 µs (200 ms) per 100000 µs (100 ms) slice is worth 2.0 cores (p. 20). The second is the automaxprocs library, which reads the cgroup files at startup (p. 21).
What you take away: since Go 1.25, Go can read the container's allowance itself and set GOMAXPROCS accordingly, but not always. Two things must be true at once. First, the Go version that compiles your program must be 1.25 or newer. Second, the go line of your go.mod file (the one that states the Go version the project targets) must say 1.25 or more. If either one is too old, Go counts the machine's cores as before, and the trap is back.
There are two ways to fix it. The cleanest: set GODEBUG=containermaxprocs=1, which turns back on only that behavior. The other: raise the go line to 1.25, but that also turns on other Go 1.25 changes that you may not have chosen.
2At startup, Go prepares your variables by their needs, not in the order you wrote them
Before opening a restaurant, you prepare the kitchen. You don't make the sauce before taking out the tomatoes. A Go program does the same before it starts main, its starting function. It first prepares its global variables, the ones written outside any function. Each one may need another. This preparation is called initialization.
The book gives an example where the writing order looks wrong (p. 33):
var (
	client      = createClient(apiEndpoint, timeout)
	apiEndpoint = baseURL + "/v1"
	baseURL     = "https://api.example.com"
	timeout     = 30 * time.Second
)
client needs apiEndpoint and timeout. apiEndpoint needs baseURL, written further down. You expect an error at compilation, the step where Go turns the code into a program. Yet it compiles and works (p. 33).
Go does not read the list from top to bottom. It takes the first variable in the list whose needs are all ready, prepares it, then starts again. Here: baseURL, apiEndpoint, timeout, then client (p. 34).
Once the variables are ready, Go runs the init() functions. You write them, but you never call them: Go runs them by itself, before main. What are they for? A library, or package (a folder of Go code, like fmt), uses one to set itself up at startup. The image/png package, for example, announces itself that way as a reader of PNG files.
Several init() functions can follow each other: in what order? Within a file, from top to bottom. Between files, Go follows the order of the names: a.go, then b.go, then main.go (p. 34). Rename a.go to z.go and its init() runs last.
So avoid having an init() rely on another. Imagine one that opens the configuration, and another to read it. After a file rename, the second runs first and reads nothing. The book warns: "A simple file rename can break the initialization logic" (my translation, p. 35). My advice, outside the book: write init() functions rarely, and put in main whatever must happen in a precise order, where it can be read.
All this work is paid for at startup. To see how much, build with go build -o app, then run GODEBUG=inittrace=1 ./app (the GODEBUG environment variable, seen in idea 1). The program writes one line per package that has initialization work. Here is the line for the example above. Its initialization is preparing its four variables:
init main @0.42 ms, 0.005 ms clock, 64 bytes, 2 allocsThe figure before clock is how long the package's initialization took, here 5 microseconds. @0.42 ms says when it started, after launch. The rest is the memory requested: 64 bytes, in 2 requests. The times change a little at each launch. If the duration before clock for a package climbs, look at what it does at startup (network, file, heavy computation).
My tests, outside the book. I replayed the book's example. The order is indeed the one in the diagram, and the inittrace line above is its real output. With three files, renaming a.go to z.go does make its init() run last. The image/png case comes from Go's own code.
3A shared boolean is not a signal: only synchronization gives a guarantee
A cook prepares the dish, then raises a flag. The waiter waits for the flag, then carries the dish away. Nothing more natural. But nothing is guaranteed without synchronization, a point where two goroutines agree with each other (a channel or a lock, for example). In Go, this is written with two goroutines running in parallel. It is the book's "classic trap":
// ✗ BEFORE: the book's code
package main

import "fmt"

var ready bool
var data int

func producer() {
	data = 42
	ready = true
}

func main() {
	go producer()
	for !ready {
	}
	fmt.Println(data)
}
The book states the reasoning one is tempted to make: "The reasoning seems logical: If ready = true, then data = 42 must have been executed before." (my translation, p. 43). Then it breaks it. To go faster, the compiler or the processor may run two independent writes in the other order (p. 43). That is allowed when nothing depends on their order, seen from a single goroutine. The goroutine that reads can then see the case "ready = true, data = 0 (ready written but not yet data: the bug)" (my translation, p. 44).
Inside a single goroutine, Go guarantees the result of the written order. Between two goroutines, nothing of the sort. Imagine each cook keeping a personal notebook. The cache is the small fast memory of each processor core, its notebook, where it copies what it uses. When the cook notes "dish ready" in theirs, the waiter, who reads another notebook, does not necessarily see it yet: each core sees writes at its own pace (pp. 43-44). Nothing forces "dish placed" to reach the waiter's notebook before "dish ready" either. These notebooks are an image, not the exact workings of the hardware. The guarantee comes from a rule the book calls happens-before. It links two events, A and B, and says: "A will be observable by all goroutines before B becomes observable" (my translation, p. 45), if A happens before B. In plain terms: whatever A wrote is visible when B runs. For us, data = 42 already happens before ready = true, in the same goroutine. What is missing is a link between the write of ready and its read by the other goroutine.
What remains is to create that link, and an ordinary flag does not create one. The book gives the table (pp. 52-53). Four tools create it:
| Tool | What it is | What happens before |
|---|---|---|
| Channel | a pipe between goroutines | the send happens before the receive |
| Mutex | a lock that lets only one goroutine through at a time | Unlock happens before the next Lock |
WaitGroup | a counter that waits for a group of goroutines to finish | Done happens before the return of Wait |
| Atomic | a read or a write done in one piece, with nobody slipping in between | a Store happens before the Load that reads its value |
So it is enough to make ready an atomic: write it with Store, wait for it with Load.
// ✓ AFTER: ready becomes an atomic
package main

import (
	"fmt"
	"sync/atomic"
)

var ready atomic.Bool
var data int

func producer() {
	data = 42
	ready.Store(true)
}

func main() {
	go producer()
	for !ready.Load() {
	}
	fmt.Println(data)
}
data stays an ordinary variable: the Store of ready happens before the Load that reads it, so the earlier write to data is visible too.
The book's program (before) has a data race: two goroutines touch the same variable, at least one writes it, with no synchronization between them. I ran the book's program with Go 1.26.6 on amd64. It prints 42. go vet, Go's code analyzer, says nothing. The race detector (-race), on the other hand, speaks up (excerpt, two alerts in all, one on ready and one on data):
$ go run -race main.go
WARNING: DATA RACE
Write at 0x000000622288 by goroutine 8:
  main.producer()
...
Previous read at 0x000000622288 by main goroutine:
  main.main()
...
42
Found 2 data race(s)
With the atomic.Bool, the same program prints 42 and -race stays silent.
The reflex: run your tests with -race. It is the only tool that sees this bug.
A neighboring trap: the end of a goroutine links nothing either. The book writes it in capitals in a box: "THE TERMINATION OF A GOROUTINE ESTABLISHES NO HAPPENS-BEFORE RELATION" (my translation, p. 50). Knowing it has finished is not enough to see what it wrote: you need a WaitGroup or a channel. Remember this: to tell another goroutine "it's ready", never use an ordinary variable.
My own test, outside the book. I never saw the ready = true, data = 0 case appear on amd64. I looked for it in 3000 runs of the book's program. I also looked in about 22 million rounds where ready turned true, with 1 to 96 pairs of goroutines. So I do not claim it. The program "works" on every run, and that is the trap: a green test does not prove there is no race.
4An object costs its size class: one more pointer can cost 64 bytes
Ask Go for room for 64 pointers. A pointer is a memory address of 8 bytes, so that makes 512 bytes. Go reserves exactly 512 for you. Add a single pointer, 65 in all: 520 bytes requested, and Go reserves 576. Eight more bytes on the request, sixty-four more on the reservation. Where does the jump come from?
Go does two things, in this order. First, it sticks a small 8-byte label, the header, on objects over 512 bytes that contain pointers. Then it puts the whole thing into the smallest ready-made slot that holds it: slots only exist in fixed sizes, such as 512 or 576. The 64-pointer array is exactly 512 bytes: no label, and it fits the 512 slot.
This sorting is the job of the allocator, the part of the runtime (Go's engine, embedded in every Go program) that hands out memory. Each request made to it is an allocation, and an object is anything you allocate: struct, array, string. It never cuts to the exact size. The book puts it this way: "Instead of allocating exactly the requested size, the allocator rounds up to the nearest larger size class." (my translation, p. 57).
These fixed sizes, the slots, are the size classes: "The runtime defines exactly 67 size classes, from 8 bytes to 32 KB" (my translation, p. 58). The first ones climb by 8 (8, 16, 24, 32), then the gap widens. Think of a station luggage office: a bag too big for the 24 compartment takes a whole 32 compartment. The extra room stays wasted as long as the bag is there. The book gives a real case: "When a 25-byte object is allocated, it occupies a 32-byte class, wasting 7 bytes" (my translation, p. 66).
Let us check with real objects: I keep 2000 of them alive, then divide by 2000 the number of bytes Go allocated. In the code, TotalAlloc counts the bytes allocated since the start of the program and KeepAlive stops the objects from being freed too early:
package main

import (
	"fmt"
	"runtime"
	"unsafe"
)

func cost[T any](name string) {
	const n = 2000
	kept := make([]*T, 0, n)
	var before, after runtime.MemStats
	runtime.GC()
	runtime.ReadMemStats(&before)
	for i := 0; i < n; i++ {
		kept = append(kept, new(T))
	}
	runtime.ReadMemStats(&after)
	var zero T
	fmt.Printf("%-10s asked %4d  paid %6.1f bytes\n", name, unsafe.Sizeof(zero),
		float64(after.TotalAlloc-before.TotalAlloc)/n)
	runtime.KeepAlive(kept)
}

func main() {
	cost[[24]byte]("[24]byte")
	cost[[25]byte]("[25]byte")
	cost[[33]byte]("[33]byte")
	cost[[64]*int]("[64]*int")
	cost[[65]*int]("[65]*int")
}
[24]byte asked 24 paid 24.0 bytes
[25]byte asked 25 paid 32.0 bytes
[33]byte asked 33 paid 48.0 bytes
[64]*int asked 512 paid 512.0 bytes
[65]*int asked 520 paid 576.0 bytesThe second line follows the book: 25 goes to 32. The others are from my test (Go 1.26.6): 24 fits exactly, 33 goes to 48. The last two lines are our puzzle from the start: 64 pointers keep 512 bytes, 65 take 576. The jump comes from the header, where Go notes the object's type (p. 64).
My array of 65 pointers is 520 bytes, plus 8 for the header: 528. The neighboring slots are 512, 576 and 640 (Go 1.26.6 table). It goes into the 576 one, and 48 bytes are lost.
How much room is lost on average? The book says: about 5.2% (p. 66). I checked it (Go 1.26.6): I asked Go for byte arrays of every size, from 16 bytes to 32 KB, and measured what it really reserves. If all sizes are equally common, 5.1% of the reserved memory is lost: the book is in the right ballpark. Small objects lose more: between 16 and 128 bytes, it is 8.7%. Above 128 bytes, a slot loses at most 15.8% of its size.
A single object therefore loses little. But a program that creates millions of identical objects pays the loss millions of times. For those, measure the size actually reserved, as above, before choosing how many elements go into the object.
5The allocator has three tiers: almost every request is served at each workstation's own worktop
A Go program asks for memory all the time, from hundreds of goroutines at once. If they all went through a single window, with a single lock (a passage where only one goroutine enters at a time), they would queue.
Go avoids the queue with three tiers, which the book describes (pp. 59-62). Let us go back to the kitchen of idea 1: each workstation has its own worktop, and two shared tiers sit behind it.
Each workstation therefore has a worktop, with one bin of ingredients per portion size. These are the 67 sizes of idea 4, the same for all workstations. At the start, no workstation has a bin: the first time a size is requested, it fetches one from the pantry (①). Then, when a goroutine asks for an object, it takes the next free portion in the right bin. Nobody else touches its worktop: no lock, and it is very fast.
When the bin is used up, with no free portion left (p. 62), the workstation hands it back to the pantry (②). It takes another that still has portions. There is one pantry per size, shared by all workstations, which can therefore get in each other's way. A bin handed back is not lost: when the garbage collector frees objects, portions become available again and it goes back on the green shelf.
If the pantry has no bin with portions left, it turns to the storeroom, a single one for the whole program, also shared: it makes a new one (③). When the storeroom has no room left, it orders some from the operating system, the supplier (④). Very large objects, from 32 KB up, skip the first two tiers and go straight to the storeroom (p. 61).
The book gives their real names: the worktop is the mcache, the pantry the mcentral, the storeroom the mheap. Each bin is a span, a block of memory reserved for a single size class (idea 4).
Each tier you go down costs more, because it is shared and the last one goes through the system. Yet you rarely go down. The book says of the slow path that it "remains relatively rare" (my translation, p. 62). A bin of small objects holds hundreds. A single descent therefore serves hundreds of them. In Go 1.26.6's code, a bin is 8 KB for most small sizes and up to 80 KB for the biggest: the bigger the portion, the fewer fit in a bin.
Go 1.26.6 code, outside the book. What is shared costs, what is private costs nothing. Ideas 17 and 18 show it: two neighboring counters get in each other's way, and a lock makes goroutines queue. The allocator answers by giving each workstation its own worktop. One detail of the book is outdated: it writes that each mcentral has its own mutex, a lock (p. 61). In Go 1.26.6, the pantry keeps its bins in sets that are most often changed without a lock (idea 20). Workstations still have to coordinate to share, and that costs more than the private worktop.
6The GC marks objects in three colors, while your program keeps running
The garbage collector (the GC) frees the memory of objects that are no longer useful. How does it know an object is no longer used? It does not guess. It starts from what is surely useful, then follows the pointers. An object that no path reaches is dead.
The starting points are called roots: global variables and the local variables of goroutines. The objects themselves live in the heap, the program's shared memory. The book colors every object in the heap (p. 82):
- white: not seen yet, a candidate for removal.
- grey: discovered, but its pointers have not been followed yet.
- black: fully processed.
At the start, everything is white, except the objects the roots point to: those are grey (p. 83). Then the GC repeats a loop: it takes a grey object, greys the white objects it points to, and blackens it (p. 83). When no grey is left, everything still white is out of reach: the GC frees it (p. 83). Two dead objects that point at each other stay white too, since no path leads from the roots to them. Step through the diagram.
This walk assumes nothing moves. But the program does not stop while the GC marks: it runs at the same time (p. 84), and it changes pointers along the way. That is where it gets complicated.
So the GC must respect one rule: no black object points at a white object (p. 86). Why? The GC never reads a black object again. If a black one pointed at a white one that nobody else points to, the GC would never see that white object. It would free it while it is still in use.
Here is how the program can break it. B is white and only G, a grey object, points at it. A is already black. The program writes a.field = b: A now points at B. Then it removes the pointer from G to B (g.field = nil). Only A still points at B, and the GC will not read A again. B stays white, so it is freed, while A uses it (pp. 86-87).
To prevent this, the compiler adds a small check to every pointer write, the write barrier. During marking, it greys the object being pointed at: here, B turns grey as soon as a.field = b runs, and the GC will process it. The rest of the time, it does nothing (p. 87). The diagram shows both cases.
One last risk: the program may allocate faster than the GC marks, and the GC would fall behind. The runtime then makes the allocator pay. Before receiving its memory, a goroutine must mark objects itself, and the more it allocates, the more it marks: this is the mark assist (pp. 85-86). The program therefore allocates more slowly, marking moves faster, and balance returns. For you, this shows up as goroutines slowing down during a GC cycle.
7GOGC sets when the GC runs, GOMEMLIMIT sets how much you can hold
The garbage collector of the previous idea does not run continuously: it comes by from time to time and frees the objects nobody uses anymore. When should it come? Too often, and it eats CPU. Too rarely, and memory swells, which ends badly in a container, whose memory is capped. Two settings answer these two questions.
Take an example. A program keeps 10 MB of useful objects and allocates new ones nonstop, most of which will soon be useless. The heap therefore grows. After each pass, the GC measures the live heap, the share of those objects still in use (heaplive in the book, here 10 MB). GOGC sets when it runs again: the percentage the heap must grow since that measure (p. 95). By default GOGC is 100: the GC runs again when the heap has doubled, here at 20 MB (p. 95). Each pass walks through the objects and costs CPU. Raising GOGC spaces passes out and costs memory, lowering it does the opposite. But GOGC sets no ceiling, it only sets the pace.
The ceiling comes from GOMEMLIMIT, a soft memory limit: the closer the heap gets to it, the more aggressive the GC becomes and the more often it runs, at the cost of CPU. Lower it in the diagram below: the teeth tighten.
With GOGC 100, the GC runs again when the heap reaches 20 MB: 6 passes in the window.
Soft means the limit can be exceeded. The book says so: "GOMEMLIMIT is a wish, not a guarantee" (my translation, p. 97). It lists three cases of overshoot: the live heap already exceeds the limit, a big allocation arrives all at once, or the cost of the GC would become prohibitive (p. 97). Take the first case: everything is alive, so the GC finds nothing to free and runs again and again. The runtime then limits the GC to about half the compute time: the other half stays with the program, so it keeps moving (Go 1.26.6 code, outside the book). The program slows down and, if it keeps allocating, memory climbs until the container kills it.
The container, for its part, has a hard limit: its cgroup caps memory. If the process exceeds it, the Linux kernel kills it: that is the OOM kill (out of memory). The advice is clear: "set GOMEMLIMIT to about 80-90% of the container limit" (my translation, p. 98). Why 80 to 90% and not 100%? Because GOMEMLIMIT is a wish: the margin leaves room for temporary allocations that overshoot it (p. 98). The book draws the moral: "only a hard system limit (cgroup) can really stop allocations" (my translation, p. 98). Stopping allocations, here, means killing the process: the cgroup limit kills, GOMEMLIMIT prevents.
One last detail surprises in a container. After a GC pass, the memory seen by the system does not drop right away. The GC frees for Go, not for the system: the freed memory stays counted in the RSS, the physical memory the system assigns to the process (p. 93). A scavenger then gives it back to the system, in the background (p. 94).
8The order of a struct's fields changes its size: 24 bytes in a mess, 16 once sorted
An object often costs more than what you ask for (idea 4). Here we shrink the request itself, without touching the program's logic: by putting the fields in a different order.
Take two structs, that is, two records that store several fields one after another in memory. They have the same four fields, written in two orders:
type Desordre struct {
	actif bool
	prix  int32
	promo bool
	stock int64
}

type Trie struct {
	stock int64
	prix  int32
	actif bool
	promo bool
}
The first weighs 24 bytes, the second 16 (measured with unsafe.Sizeof, Go 1.26.6). Same fields, a third less memory, just by changing the order. Where do the 8 missing bytes go?
Into empty space, and that space is not an oversight by Go: it is the price of a processor rule. Think of a car park with numbered spaces. A truck that takes eight spaces only parks at number 0, 8 or 16. A car that takes four starts at 0, 4 or 8, and a bicycle goes wherever it likes.
In Go, the int64 (8 bytes) is the truck, the int32 (4 bytes) the car and the bool (1 byte) the bicycle. Each value must start at an address that is a multiple of its size: this is alignment (p. 163). The processor then reads it effortlessly.
Go lays the fields out in the order you write them, "without ever changing the order specified in the source code" (my translation, p. 166). When the next field does not land on an allowed address, Go leaves empty bytes to bring it there: this is padding. The diagram shows our two structs, one row per group of 8 bytes.
In Desordre, actif takes byte 0. prix cannot start at byte 1: it waits for byte 4, and 3 bytes stay empty. promo takes byte 8. stock must start at a multiple of 8, so at 16, and 7 more bytes stay empty. Total: 24 bytes, 10 of them empty.
In Trie, the truck goes first and takes bytes 0 to 7. prix sits right behind it, from 8 to 11, then actif and promo take bytes 12 and 13. No gap left to make up. Two remain at the end: a struct is rounded up to a multiple of the alignment of its largest field, here the int64, so 8 (p. 166). Without this rounding, the second struct of an array would start at byte 14, an address forbidden for its int64.
A single struct gains almost nothing. A million Desordre take 24 MB, a million Trie 16 MB. Sorting therefore matters for structs created by the million: points, events, rows of a catalog kept in memory.
The rule to remember: biggest to smallest. The book writes it so: "simply sort the fields from largest to smallest" (my translation, p. 169). A bigger size is a multiple of the smaller ones: after an int64, the address already suits an int32, so no gap between fields.
No need to count by hand: the fieldalignment tool, installed with go install, spots wasteful structs. On Desordre, my run prints Desordre has size 24 but the optimal size is 16 leading to a waste of 8 bytes (33%).
The book names one caveat: fields read together are better kept side by side (p. 169), because the processor loads memory in 64-byte blocks: two neighboring fields arrive together, two distant fields may need two loads. So sort where it weighs, and measure.
My run, Go 1.26.6. I read the positions with unsafe.Offsetof, 0, 4, 8 and 16 for Desordre, 0, 8, 12 and 13 for Trie, as in the diagram. The fieldalignment message is today's, wordier than the book's (p. 170).
9A slice weighs only 24 bytes: copying it does not copy its data
A slice is Go's resizable list, written []int for a list of integers. Writing b := a does not copy the list, and here is why. A slice variable is a small record (a struct). The book gives its weight: it "takes exactly 24 bytes on a 64-bit architecture" (my translation, p. 184). It has three fields of 8 bytes:
array: the address of the slice's first element, inside a backing array, the memory zone where the values are stored. It is not necessarily the start of that array (p. 185).len: the number of elements in the slice.cap: the capacity, meaning the number of elements reachable fromarrayto the end of the backing array.
Copying a slice therefore means copying these three fields, which the book calls the header. It puts a number on the contrast: "A []int of 1 million elements is copied in 24 bytes (slice header), not 8 MB" (my translation, p. 448). The copy is fast, but both slices then look at the same array (p. 190):
a := []int{10, 20, 30}
b := a             // copies the header, shares the array
a[1] = 99
fmt.Println(b[1])  // 99
a = append(a, 40, 50) // capacity 3 exceeded: new array for a
b[0] = 77             // b keeps the old array
fmt.Println(a[0]) // 10An append adds elements at the end, and it only looks at one thing: is there room left in the array? Here, a has a length of 3 and a capacity of 3, so the array is full. A literal slice has a capacity equal to its length, so "Any later append will trigger a reallocation" (my translation, p. 188). To add 40 and 50, Go allocates a bigger new array and copies 10 20 30 into it. It adds 40 and 50, and a now points to that array. b has not moved: its header still aims at the old array, and b[0] = 77 writes only there. The new array doubles the capacity up to 256 elements, then grows more gently. Its size is then rounded up to a size class from idea 4 (Go 1.26.6 code, outside the book).
When there is room left, it is the other way round: append writes into the existing array, so into the other slices that look at it too. Take an array of eight values, data := []int{0, 1, 2, 3, 4, 5, 6, 7}. A window on it, w := data[2:5], looks at cells 2, 3 and 4: [2 3 4]. Its length is 3. The 5 limits what it sees, not what it reaches: behind it, the array goes on. Its capacity is 6: it is the number of cells between its start, cell 2, and the end of the array, cell 7 (p. 188). A slice does not step back, it only grows to the right. Those 6 cells are therefore the room it has without changing array.
What does w = append(w, 99) do? There is room left, so Go writes 99 into the next cell, cell 5. That cell also belongs to data: data[5] was 5 and is now 99 (my test, Go 1.26.10). We changed data without meaning to, through the window.
Go lets you close the window with a third index. v := data[2:5:6] looks at the same cells 2 to 4, but its capacity stops before cell 6: it is 4 (p. 188). A first append can still write into cell 5. The next one has no room left and creates a new array: cells 6 and 7 of data stay safe (my test, Go 1.26.10).
To truly isolate, the book advises defensive copies: copy the data into a new array before lending it (pp. 189, 193). Remember this: a slice you receive is not yours, it is someone else's array being lent to you. Three habits are enough. Always keep the result of append: a = append(a, x). Do not modify a received slice without saying so. For an array of your own, copy with slices.Clone(a). To lend without risk of overflow, close the window with slices.Clip(a) (my test, Go 1.26.6).
10A string is bytes, not text
A file from an old system contains "café", written in an old encoding, ISO-8859-1, where the é fits in a single byte. Your Go program reads it, turns it into a list of characters, then rebuilds it. The text has changed, and nobody noticed.
s := "caf\xe9 !" // "café" in ISO-8859-1: the é fits in a single byte
fmt.Println(len(s), utf8.ValidString(s)) // 6 false
rebuilt := string([]rune(s))
fmt.Println(rebuilt == s, len(rebuilt)) // false 8
A Go string is a small record with two fields: a pointer to bytes and a length in bytes (p. 206). It is the header of a slice from idea 9, without the capacity. Nothing in it says these bytes form text: "Go strings, as a data type, simply store a sequence of bytes without intrinsic encoding validation" (my translation, p. 203). Yet some operations assume UTF-8, the standard Unicode encoding where a character takes 1 to 4 bytes: "By default, Go considers that a string contains UTF-8 and automatically tries to decode it" (my translation, p. 205). That is the case for range and for the conversion to []rune, a list of runes, the characters as Go sees them.
In my example, the lone byte 0xE9 is not valid UTF-8. Decoding does not crash: it puts the replacement character U+FFFD in its place, the "�" (p. 205). That character takes three bytes in UTF-8, hence the 6 bytes that became 8: 3 for caf, 3 for the replacement, 2 for the space and the exclamation mark. string([]rune(s)) is therefore not a faithful copy (my test, Go 1.26.6).
The string's two fields explain a second trap. Slicing a string copies nothing: big[:10] is a new record, of length 10, pointing at the start of the same bytes. As long as that substring lives, all the original bytes stay in memory, even those nobody uses anymore. The book: "A small substring of a few characters can prevent the release of a string of several megabytes" (my translation, p. 210).
big := strings.Repeat("x", 10_000_000)
start := big[:10]             // points into the 10 MB
start = strings.Clone(start) // copies 10 new bytes, the 10 MB can goI kept five 10-byte beginnings, each taken from a 10 MB string. After a pass of the garbage collector, the program takes 50.5 MB, against 0.5 MB at the start. With strings.Clone, it falls back to 0.5 MB (my test, Go 1.26.6).
Remember this: for text coming from outside, check it with utf8.ValidString before decoding it. To keep a small piece of a big string, copy it with strings.Clone.
11A map never shrinks, even when emptied
After lists, tables. A map (map[string]int) associates keys with values. Imagine lockers: eight lockers fill up to 52 pairs, which is 6.5 per locker on average. Here are the names. The runtime turns each key into a number, the hash, which designates a bucket: a storage cell holding up to eight key-value pairs (p. 217). The load factor is the average number of elements per bucket. When it exceeds 6.5, the map grows: Go doubles the number of buckets and copies the elements into them (pp. 220-221). The book sees in it "the best observed compromise between memory use and access performance" (my translation, p. 220).
Two points follow: the size, which still holds, then the date. First the size. A map never gives its space back: "Go maps never shrink automatically" (my translation, p. 223). The book's example: "A map that once held a million elements will keep its buckets (about 262,000) even after all elements are deleted" (my translation, p. 224).
But why can't the garbage collector do anything about it? My explanation, valid for the old model (before Go 1.24, see below): the buckets form a single block array, which the map references as long as it exists. Deleting an element empties a cell of this block without returning it. For Go 1.26, where there are no buckets any more, I only have the measurement below.
My test confirms it. For a million integers, the heap weighs 36 MB with Go 1.26 (38 MB with Go 1.23). It weighs the same after deleting all the elements, and the same after clear (the function that empties a map). It falls back to 0 MB only when the variable referencing the map is set to nil: nothing references the map any more, so the GC frees it. The book's remedy is therefore sound: "consider recreating the map periodically" (my translation, p. 224). You build a new map with the remaining elements, and the GC frees the old one. Think of application caches and session tables that went through a peak.
The second point is a date. Since Go 1.24, maps are no longer made of buckets but of Swiss Tables (box below). The book's model is exact up to and including Go 1.23, tested with Go 1.23.12. Yet the book is based "mainly on Go 1.26 and later versions" (my translation, p. xxviii). The word Swiss appears nowhere in it (0 occurrences in the 604 pages).
One figure in the book is wrong even in the old model. For make(map[string]int, 1000), it announces about 1024 buckets and "up to about 6,600 elements without resizing" (my translation, p. 226). It counted one element per bucket. I get 256 buckets with Go 1.23.12: 1000 ÷ 6.5 is about 154, rounded up to the next power of 2. That gives 1664 elements at most (6.5 × 256).
Outside the book, Go release notes. Since Go 1.24, maps are Swiss Tables, a different hash table design. A table holds at most 1024 slots, the cells that each receive one key-value pair, arranged in groups of 8. It fills at most to 7/8: the maximum occupied space, like the load factor but as a share of the cells. There are no buckets any more. With Go 1.26, make(map[string]int, 1000) creates two tables of 1024 slots (my test). Let's count: 1024 × 7/8 = 896 elements per table, fewer than 1000, so two are needed. The book's figure of 1024 buckets therefore matches neither Go 1.23 nor Go 1.26. Still true: the map does not shrink, iteration order is random (p. 224), an unprotected concurrent access is detected (idea 15), and make(map, n) pre-sizes. Sources: Go 1.24 release notes and the go.dev/blog/swisstable post.
12An interface is two words: a nil that is not nil, and an integer that allocates
A function finds no error, and its caller sees one anyway. Here is the function. Its return type, error, is an interface: a variable that can hold any value that has an Error() method.
package main

import "fmt"

type MyError struct{}

func (*MyError) Error() string { return "failure" }

func open(fail bool) error {
	var err *MyError
	if fail {
		err = &MyError{}
	}
	return err
}

func main() {
	err := open(false)
	fmt.Println(err != nil) // true
	fmt.Printf("%T\n", err) // *main.MyError
}
An interface variable is two words of 8 bytes, 16 bytes in all (p. 231). The first designates the type of the value stored inside, the second the value itself. The book settles the nil question in one sentence: "An interface is nil when its first field is nil." (my translation, p. 236). Now err is a *MyError that is nil, and at the return Go stores it in an error: "This conversion creates a new interface that wraps both the type *os.PathError and the value nil." (my translation, p. 236). The book writes *os.PathError here: in our example, it would be *MyError. The first word holds *MyError, so it is not nil. The second is nil. The err != nil test answers true.
The book offers two ways out (p. 237): write return nil when all went well, or declare the variable with type error rather than the concrete type.
The second word also explains a cost. Picture the interface as an envelope with two slots: the type, and the address of the value. To have an address, an integer must first be put on a shelf, that is allocated on the heap, the program's shared memory (idea 6). The book claims the opposite. Values the size of a pointer "are stored directly in the data field of the eface without extra allocation" (my translation, p. 238). The eface is the internal name of the empty interface, any. Strings would be a special case: "they contain a pointer to the data and a length, so they fit in the available space" (my translation, p. 238). But a pointer and a length make two words, and the field has one. The section does open on the right observation: a value stored in an empty interface can allocate (p. 238).
I counted the allocations when the value is stored in a global variable sink, so that it outlives the function:
var sink any

func main() {
	n := 999 + len(os.Args)   // 1000, known only at run time
	small := len(os.Args) + 6 // 7
	s := os.Args[0]
	p := new(int)
	fmt.Println("integer 1000 :", testing.AllocsPerRun(1000, func() { sink = n }))     // 1
	fmt.Println("integer 7    :", testing.AllocsPerRun(1000, func() { sink = small })) // 0
	fmt.Println("string       :", testing.AllocsPerRun(1000, func() { sink = s }))     // 1
	fmt.Println("pointer      :", testing.AllocsPerRun(1000, func() { sink = p }))     // 0
	fmt.Println("constant     :", testing.AllocsPerRun(1000, func() { sink = 1000 }))  // 0
}
The runtime code explains the rest (Go 1.26). For an integer, convT64 returns the address of a static table if it is below 256, otherwise it allocates 8 bytes. For a non-empty string, convTstring allocates 16 bytes.
Remember two things. A function that returns error returns nil or a real error, never a typed variable. And in a loop called often, storing an integer or a string in an any costs an allocation when the value leaves the function: measure with testing.AllocsPerRun before believing a rule, even a book's.
13Capturing a variable costs nothing: it is the closure that escapes that you pay for
A counter in Go takes a few lines. The function retourneAvecModif creates n := 0 and returns func() int { n++; return n }, a closure: a function that keeps access to the variables of the function that created it. Here, it increments n. Two memory areas come into play. The stack is a function's workbench: it is cleared when the function returns. The heap, met in idea 6, is a warehouse: only the garbage collector empties it, once nobody uses the object. A question arises: where does n live once retourneAvecModif has finished? On the stack, it would disappear with its function. This one has to survive.
The book answers: "Closures in Go capture the variables of their enclosing context by reference" (my translation, p. 513). By reference means that the closure and the function share the same variable, with no copy. My test confirms it: after x := 1 and f := func() int { return x }, the assignment x = 99 makes f() return 99.
The compiler can nevertheless cheat when nobody would see the difference. It then copies the value into the closure: this is capture by value. The book reserves it for variables that meet three conditions at once (p. 284):
- a size less than or equal to 128 bytes;
- no reassignment after the closure is created;
- "an address never taken with the & operator in the code" (my translation, p. 284).
The -gcflags=-m=2 option (for example go build -gcflags=-m=2) prints the compiler's decision, variable by variable, and width there means the size in bytes:
func retourneSansModif(n int) func() int {
    return func() int { return n * 2 } // n never reassigned
}

func retourneAvecModif() func() int {
    n := 0
    return func() int { n++; return n } // n reassigned
}
retourneSansModif capturing by value: n (addr=false assign=false width=8)
retourneAvecModif capturing by ref: n (addr=false assign=true width=8)
moved to heap: nThe moved to heap line says n left the stack for the heap: otherwise it would disappear with its function. In my test, the returned closure costs 1 allocation with capture by value, and 2 with capture by reference. A 200-byte array, even never reassigned, is captured by reference and also goes to the heap: the book's 128-byte limit is exact.
The cost then depends on whether the closure gets out. The compiler runs an escape analysis: it checks whether the closure leaves the function that created it, because it is returned or started with go. If it does not leave, the variable stays on the stack, even captured by reference. Minimal case: called in place, the closure makes 0 allocations, returned it makes 1 or 2. The book writes it: "Otherwise, it can stay on the stack depending on escape analysis." (my translation, p. 284). Yet it also writes: "Variables captured by reference require a heap allocation." (my translation, p. 515). The two sentences cannot both be true. The test backs the first. Even the book's own testClosure example (p. 515), whose err variable is nonetheless reassigned, makes 0 allocations. No moved to heap line appears.
My test, with caution. The book measures a billion counter++ and finds, on x86, that the code with a closure is "about 7.4 times slower" than the direct code (my translation, p. 514). It notes itself that on ARM the expected gap does not reproduce: 224 ms against 268 ms, so 1.2 times. I replayed the book's program with Go 1.26.8 on a recent laptop with an AMD processor: 222 ms with the closure, 210 ms direct, so about 1.05 times. The factor therefore depends on the machine.
What you take away: a closure called in place is almost free. You pay when it leaves its function, and only -m=2 tells you what the compiler decided for each variable.
14An unrecovered panic in a goroutine kills the whole program
After the types, the end of a program. Here the book makes its most dangerous mistake, because it writes it four times. Four words first:
- a goroutine is a function started with
go f(): it runs in parallel with its caller. - a defer schedules a call for the end of the function, for example closing a file.
- a panic is an emergency stop: the function is interrupted and its
defercalls run. Then the panic goes up to the calling function, and so on. - a recover, placed in a
defer, stops the climb.
A goroutine has no caller. If the panic reaches the end of its first function without meeting a recover, it has nowhere left to go. What happens then? The book first answers that it stays contained: "a panic in a goroutine only affects that goroutine and does not propagate to the others" (my translation, p. 296). It repeats it: "a panic ends the faulty goroutine but not the whole program (except for the main goroutine)" (my translation, p. 309), then in the chapter summary (p. 314) and in the chapter on goroutines (p. 383).
Three passages say the opposite, and they are right. The clearest: "Whatever the goroutine (main or not), an unrecovered panic triggers the runtime.fatalpanic function, which ends the whole program" (my translation, p. 313). Pages 383 and 384 say it again, and page 383 even says both, a few lines apart. The book contradicts itself. Its own example settles it. The first goroutine panics, the second waits 100 ms then prints a message, and the main goroutine waits 200 ms:
go func() { panic("goroutine 1") }()
go func() { time.Sleep(100 * time.Millisecond); fmt.Println("goroutine 2 continue") }()
time.Sleep(200 * time.Millisecond)
fmt.Println("main continue")
The text after this example says: "the panic of the first goroutine ends the whole program" (my translation, p. 384). I replayed the example with Go 1.26.10. The program prints panic: goroutine 1, then exits with a non-zero exit code (p. 314). That code is the number every program hands back to the system when it stops, 0 if all went well. Here it is 2. Neither "goroutine 2 continue" nor "main continue" appears. If the faulty goroutine contains defer func() { recover() }(), the program carries on.
Remember the rule, not the book's sentence: every goroutine you start must protect itself with a recover, otherwise a single panic stops the whole service.
15A defer does not run when the program stops abruptly
The recover of the previous idea lives in a defer. But a defer is not as safe as the book lets you believe. The book presents it as a guarantee: the call happens "whether this termination is normal or due to a panic" (my translation, p. 288). It adds that "This guarantee of execution makes it a particularly handy tool for resource management" (my translation, p. 288).
This guarantee has at least four exceptions. In my test under Docker, a defer that calls recover runs in none of them:
os.Exit(3): the program stops on the spot with exit code 3, without running anydefer.- two goroutines writing to the same map without a lock: the runtime stops everything. A lock (mutex) lets only one goroutine through at a time. The book shows this message,
fatal error: concurrent map read and map write(p. 225). - a total deadlock (deadlock): all goroutines are waiting, and none can move on.
- endless recursion, which overflows the stack, the memory zone where a goroutine piles up the function calls in progress.
The last three cases are fatal errors, stops decided by the runtime itself. An unrecovered panic, for its part, first runs the defer calls of its goroutine (idea 14). A fatal error stops without running any. os.Exit does the same without being a fatal error: the program asks for it. The book does not say so: between pages 288 and 314, devoted to defer and panics, it contains neither os.Exit nor fatal error (0 occurrences). A neighbouring case appears only on page 383: goroutines still running when the program stops are killed without running their defer calls.
Read in the standard library code. log.Fatal calls os.Exit(1). A log.Fatal in main therefore skips the defer calls of main. Concrete case: move the work into a function run() error that holds the defer calls and returns normally. Only main then calls os.Exit(1) if run returns an error, and the defer calls of run have already run.
The rule: a defer protects the exit of a function, even through a panic. It does not protect the stopping of the whole program.
16An iterator that ignores the loop's break crashes on the first break
Since Go 1.23, a for v := range loop accepts a function in place of a slice or a map. That function is an iterator: it produces values one by one. It receives another function as a parameter, named yield by convention, which it calls once per value. The loop looks like any other. The trap hides underneath.
The compiler indeed cuts the loop in two. The body, between braces, becomes a small function, a closure (idea 13). That closure is what the iterator receives under the name yield. The book describes it this way: "the body of the loop is extracted into a separate closure" (my translation, p. 317). Each turn of the loop is therefore a call to yield.
A break or a return in the body makes the closure answer false. The iterator must then stop: "If yield returns false, the iterator must immediately stop producing values and stop." (my translation, p. 316). Here is an absent-minded iterator:
func Distrait(yield func(int) bool) {
    for i := 0; i < 5; i++ {
        yield(i) // the return value of yield is ignored
    }
}

func main() {
    for i := range Distrait {
        if i == 2 {
            break // panic here
        }
    }
}
With Go 1.26.8, Distrait works as long as the loop runs to the end. At the break, the runtime detects that the iterator kept going and stops with panic: runtime error: range function continued iteration after function for loop body returned false. The bug therefore shows up only with the first caller who breaks out of the loop, sometimes long after the iterator was written. The fix takes one line: if !yield(i) { return }.
The cutting has one last effect, on defer. Since the body is a closure, you might think the defer runs at the end of each turn. It does not: "a defer always attaches to the function in which it syntactically appears, not to the closure generated by the compiler" (my translation, p. 321). Here is the test, where Bon is the same iterator with if !yield(i) { return }:
func essai() {
    for i := range Bon {
        defer fmt.Println("defer du corps, i =", i)
        if i == 1 {
            break
        }
    }
    fmt.Println("fin de la boucle")
}
With Go 1.26.8, essai() first prints "fin de la boucle", then defer du corps, i = 1, then defer du corps, i = 0. The defer calls wait for the return of the function that contains the loop, as in an ordinary loop.
My measurements and Go's source code. The book speaks of a "non-negligible execution cost" (my translation, p. 322) without putting a number on it. On 65,536 integers and a trivial loop body, the loop over a function costs about 0.45 to 0.5 ns per element. A range over a slice costs 0.22 (Go 1.26.8). It is an order of magnitude, and it depends on the machine. The book also presents as an error an iterator that ends without having received false (p. 320). That is in fact the normal case, which does not panic.
17Two neighboring counters slow each other down: 56 bytes of empty space fix it
Last setting, processor side. Picture two colleagues each annotating a different line of the same photocopied page. As soon as one writes on the page, the other must recopy the whole page before going on, even though they never touched their own line. Now the technical words. The processor does not read memory byte by byte but in blocks, the cache lines, of "generally 64 bytes" (my translation, p. 401). Each core keeps in its cache, the fast memory met in idea 3, a copy of the lines it uses. When one core writes to a line, the copies of the other cores are stale: they are said to be invalidated (p. 401), and each core must reload the line before using it. The counters below go through atomic operations, like Add on an atomic.Uint64 (idea 3).
Transpose that to memory: two independent counters, side by side. They end up in the same line. Two cores each increment one of them. Each write invalidates the copy of the line on the other core, which must reload it. The counters share nothing, but they slow each other down. This is false sharing. The book proposes padding: a silent field, written _, that forces each counter onto its own line. It is [56]byte, that is "64 - 8" (my translation, p. 402): a 64-byte line minus the 8 bytes of a Uint64 counter. The second _ also isolates the last counter from whatever follows it in memory.
type GoodMetrics struct {
    atomic_counter_1 atomic.Uint64
    _                [56]byte // 64 - 8 = 56
    atomic_counter_2 atomic.Uint64
    _                [56]byte
}My own benchmark. The book gives no figure for this gain. It only writes that sharding with appropriate padding improves performance "drastically under heavy load" (my translation, p. 401). I measured two goroutines each doing 100 million Add calls, with Go 1.26.10. Without padding: 1.58 to 1.72 s. With padding: 0.17 to 0.18 s. That is 9 to 10 times faster over three runs, at the cost of a structure growing from 16 to 128 bytes. The figure depends on the machine.
What you take away: keep padding for counters hit hard by different goroutines. Everywhere else, it wastes memory. The book also measures another slowdown. It has a growing number of goroutines do 500 million increments. The task takes 0.15 seconds in a loop with no atomic, the baseline. With a single atomic counter shared by 7 CPUs, it takes 133 times longer (pp. 400-401). That is contention: goroutines modifying the same variable get in each other's way.
Padding alone cannot help, since there is only one variable. The book advises splitting it into several counters, spread by goroutine, CPU number or hash. You add them up at read time, and you separate them "with appropriate padding" (my translation, p. 401). An atomic is fast alone, not under contention.
18A channel is a lock with a queue, and an RWMutex is not a faster Mutex
Two common-sense reflexes. A channel is too slow: add a buffer. A Mutex hinders readers: swap it for an RWMutex. In both cases you expect to win. In both cases you can lose, for the same reason: every operation crosses a shared point, a lock or a counter, that all goroutines pass through in turn.
A channel is a pipe between goroutines: one sends with ch <- v, the other receives with <-ch. A buffer adds slots where values wait. Under the hood, the channel is a runtime structure that holds a lock, a ring of slots and two queues of sleeping goroutines: those that want to send, those that want to receive. Think of a counter window: you go in one at a time through the door, which is the lock. On the shelf, the slots hold the values, and two queues wait outside. Every send and every receive takes this lock, buffer or not. The book says so: "The buffer reduces how often goroutines block, but not how often the mutex is accessed." (my translation, p. 443). The buffer avoids waits, not trips through the lock. To make fewer trips, you must send fewer times, so send batches of values:
ch := make(chan int, 100)
for i := 0; i < n; i++ {
    ch <- i // one trip through the lock for each value
}

batches := make(chan []int, 10)
batch := make([]int, 0, 100)
for i := 0; i < n; i++ {
    batch = append(batch, i)
    if len(batch) == 100 {
        batches <- batch // one trip for 100 values
        batch = make([]int, 0, 100)
    }
}
if len(batch) > 0 {
    batches <- batch
}
The book sees this gain: sending in batches divides the number of operations by the batch size (p. 444). My test: 5 million integers, one producer, one consumer, Go 1.26.8. Without a buffer, 104.5 ns (nanoseconds) per value. With a buffer of 100, 23.0 ns (4.6 times faster). With batches of 100, 3.7 ns (28 times faster). The book announces that "a buffer of appropriate size can multiply throughput by a factor of 10 to 100" (my translation, p. 443). On my machine, the buffer alone gives 1.3 to 4.9 times depending on its size (from 1 to 1000). The factors of 13 to 35 come from the batches. These figures depend on the machine.
A mutex is simpler: when nobody is waiting, Lock does a single atomic test. Otherwise the goroutine goes to sleep in a queue, as in the channel (read in Go's code, outside the book).
The RWMutex is a lock with two doors: several readers enter together, one writer enters alone. You conclude that it beats the Mutex when you read a lot. Not always. Every read takes the lock, then gives it back. The book counts the price: "in the common case a read costs only two atomic operations" (my translation, p. 422). Those two operations modify the same reader counter, shared by all goroutines. Readers do not wait for each other, but they all go through that counter.
My test: 13 readers in a loop, a writer that comes in every 500 µs, 2 seconds per measurement. The protected section is the code that runs while the lock is held. When it is empty (a plain read), the Mutex does 32.6 million reads per second and the RWMutex 15.2 million: twice fewer. With a section of 1000 additions, the Mutex drops to 3.8 million and the RWMutex rises to 13.1 million: 3.5 times more. The measurement is noisy, keep the order of magnitude. The length of the section decides. The book says so too: the RWMutex becomes worthwhile when reads dominate by far and sections are "long enough" (my translation, p. 424).
The sync source code and my benchmark. The book writes that "writers can be totally starved under heavy read load" (my translation, p. 424). Being starved, here, means never getting the lock. Page 419 says the opposite: "Writers first: a waiting writer blocks new readers to avoid starvation." (my translation, p. 419). The source code backs page 419: in sync/rwmutex.go, a pending Lock makes new RLock calls wait, so that the writer eventually gets through. My benchmark confirms it: with 20 readers, the writer gets the lock 665 to 1428 times in 2 seconds, never zero. Its writes slow down, they do not stop.
What you take away: a channel or an RWMutex must be measured. Send in batches when values are small and numerous. Keep the RWMutex for overwhelmingly read-heavy cases and sections that last. In other cases, measure: a plain Mutex can be faster.
19A five-minute timeout is tested in zero seconds: testing/synctest simulates the clock
A test that really waits is slow or flaky. To check that a context (Go's context, which carries a deadline) expires after five minutes, the test sleeps five minutes. To go faster, you shorten the delay, and the test fails now and then because the machine was busy. The book names the second flaw: "This imprecision makes tests non-deterministic and causes intermittent failures." (my translation, p. 467).
The testing/synctest package changes the rule: "The testing/synctest package solves these problems by providing a simulated clock." (my translation, p. 467). The test runs in a bubble, a small isolated world. Goroutines started inside belong to it. The time package reads a simulated clock there, which starts at midnight UTC on January 1, 2000 (p. 468). This clock does not run on its own: "Time only advances when all the goroutines of the bubble are durably blocked." (my translation, p. 468).
A goroutine is durably blocked when it waits for something that can only come from the bubble: a time.Sleep, a channel created in the bubble. When all goroutines sleep like that, the runtime moves the clock to the next deadline and wakes what was sleeping. Time jumps, it no longer flows.
func TestTimeout(t *testing.T) {
    synctest.Test(t, func(t *testing.T) {
        start := time.Now()
        ctx, cancel := context.WithTimeout(t.Context(), 5*time.Minute)
        defer cancel()

        time.Sleep(5*time.Minute - time.Nanosecond)
        synctest.Wait()
        if ctx.Err() != nil {
            t.Fatal("expired too early")
        }

        time.Sleep(time.Nanosecond)
        synctest.Wait()
        if ctx.Err() != context.DeadlineExceeded {
            t.Fatal("should have expired")
        }
        t.Log("simulated time elapsed:", time.Since(start), "start:", start.UTC())
    })
}
The test sleeps five minutes minus one nanosecond, checks that the context is still alive, then sleeps the last nanosecond and checks that it has expired. synctest.Wait() waits until the whole bubble is blocked, which lets the wake-ups happen before the check. It is also a synchronization point (p. 468). With Go 1.25 in the go.mod, my test passes in 0.00s and prints simulated time elapsed: 5m0s start: 2000-01-01 00:00:00 +0000 UTC. An equivalent test without a bubble, with a 5-second timeout, takes 5.00s.
My test, and a limit of the book. The clock does not advance while a goroutine waits for a mutex or the network. The book explains: "Mutexes are excluded from durable blocking because they often protect global resources shared between the bubble and the outside." (my translation, p. 469). A lock or a connection can be released from outside, so the runtime cannot know whether the wait will end without it. For network code, the book suggests net.Pipe, an in-memory connection (p. 469). Another useful effect: a deadlock inside the bubble fails the test at once. My test, with a channel that has no sender, prints panic: deadlock: all goroutines in bubble are blocked. Without a bubble, you would wait for the default go test timeout, ten minutes.
What you take away: a test that waits for a delay does not need to sleep. The book specifies that the simulated clock works with Sleep, After, NewTimer, NewTicker, WithDeadline and WithTimeout (p. 469). One condition: the wait must go through neither a mutex nor the network.
20A few of the book's errors, easy to check
The book states everything with the same assurance: nothing in its way of writing tells true from false. Yet the author writes: "Once these mechanisms are understood, good practices follow naturally from understanding rather than from the mechanical application of rules" (my translation, p. xxviii). A badly explained mechanism therefore distorts the practices you deduce from it. Here I keep only seven, the grossest ones, those that one line of code or the book itself is enough to prove. The previous ideas already covered others, in context.
Seven errors to check yourself. For each one, the book page and what contradicts it.
- Code not to copy: slice conversion. The book says
d := []byte(c)works forcof type[]MyByte(p. 194). It does not compile. The book declarestype MyByte byte: that is a defined type, distinct frombyte, and not an alias (type MyByte = byte). - False explanation: goroutines and threads. The book writes "each waiting goroutine corresponds to a blocked OS thread" (my translation, p. 130). Yet 10,001 goroutines waiting on a channel use only 6 threads in my test: only a blocking system call, a request to the system such as reading a file, occupies one. Reminder from idea 1: Go shares few threads among many goroutines. The book itself says so elsewhere: Go "maintains a constant number of OS threads regardless of the number of connections" (my translation, p. 150).
- Figure that does not hold: 493 times faster. The book compares a stack allocation with a heap one: 0.28 ns against 140.2 ns, "a factor of ~493×" (my translation, p. 76). The first measurement is the cost of an empty loop: the variable is never used, so the compiler removes the allocation. With Go 1.25.14, I get 0.2265 ns against 244.4 ns.
- False explanation: locks and contention. The book writes "the absence of locks eliminates contention" (my translation, p. 411). Yet the same chapter measures, without any lock, the 133-fold slowdown due to contention (p. 401).
- Demonstration that proves nothing:
time.Sleep(0). The appendix writes thattime.Sleep(0)"serves as a trick to simulate preemption" (my translation, p. 480). Preemption is the runtime interrupting a goroutine to hand control to another. ButSleepreturns at once for a zero or negative duration (documentation oftime.Sleep). In the appendix program, two goroutines each increment a shared counter 10 million times. It therefore loses no update in my test, with or without preemption. Withruntime.Gosched()instead, I lose half of them. - False explanation: the instruction behind an atomic on x86-64. The book's code says
atomic.StoreInt64generates "an instruction LOCK MOV on x86-64" (my translation, p. 47). I compiled and disassembled with Go 1.26.6 on amd64: theStoregives anXCHGQ, which locks by itself, and theLoada plainMOVQ. Reading an atomic therefore uses the same instruction as an ordinary read. - Outdated detail: the mutex of each
mcentral. The book writes that eachmcentralis "protected by its own mutex" (my translation, p. 61), and that it keeps two lists,nonemptyandempty. In Go 1.26.6's code,mcentraldoes not protect its spans with a mutex: it keeps them in two pairs of sets,partialandfull, where adding and removing take no lock (a small lock only serves to grow a set). The three-tier principle stays right, but this detail is dated.
My honest take
Does this book make me understand what Go does under the hood? Yes. Can I believe what it states without checking? No, and that is the whole problem. My verdict: a good map of Go's engine, drawn with a few roads that no longer exist or never did.
Its strength: the substance of the mechanisms. I draw twenty ideas from it, across the four parts of the book: CPU in a container, the cost of an object, the header of a slice, the interface, iterators, false sharing, channels. These findings are true, concrete and useful day to day. The author even promises a sober method: the book "favors official sources" (my translation, p. xxvii) and its tone is "deliberately factual and technical" (my translation, p. xxvii). The tone holds. The method holds less well: several claims contradict Go's source code or documentation (ideas 10, 12, 16 and 18, then 19).
First reservation: nothing in the tone tells a right sentence from a wrong one. Since it is sometimes wrong, every figure, every internal name and every piece of copied code must be replayed before it enters your project. Otherwise you will copy a SetGCPercent(-1) that turns the GC off, or a slice conversion that does not compile.
Second reservation: the version. The book announces Go 1.26 in its foreword (p. xxviii). Yet it describes the maps from before Go 1.24 and ignores the CPU read from the cgroup since Go 1.25. The principles last. Internal structure names, thresholds and figures should not be quoted as they are in a code review.
My advice: read, in the book, the chapters on slices (chapter 10), panics (18), goroutines (23) and the garbage collector (5), then synchronization (24). Skim the maps (chapter 12) for the non-shrinking effect, without retaining the buckets. Skip the assembly pages, the machine code: the book itself says that skipping them does not block understanding (p. xxvii). The book says that the first two parts, Runtime foundations and Types and data structures, "are largely independent and can be read separately" (my translation, p. xxvi). Half of my ideas come from them: if you only have time for those, it is already a good return. The other two parts build on them. Replay in ten lines everything you plan to copy, as the book itself invites you to: it wants to give the reader "the elements to form their own opinion" (my translation, p. xxvii).
Generics have no idea of their own, for lack of space. Neither does goroutine scheduling, although the foreword places it at the heart of its questions: how the scheduler chooses which goroutine to run (p. xxvi). The book answers it in about forty pages (pp. 113-157). It describes each processor's run queue and the work stealing between them. It also describes the preemption that interrupts a greedy goroutine and the hand-off when a system call blocks. It adds timers, the network poller, the sysmon watchdog thread and how to read schedtrace output. Its practical conclusion fits in a few words: "write your code naturally" (my translation, p. 122).
Even on the topics covered, this review keeps to the essence of each mechanism, and the book goes much deeper. The garbage collector and memory take about thirty pages (pp. 82-112): the detail of marking, reading the ReadMemStats metrics, the gctrace output, pprof profiles. If one of the ideas above made you want to dig, the book is the one to open.
Odilon
Still valid in 2026?
Largely. The principles hold: a slice shares its array, a map does not shrink, an unrecovered panic stops everything (the book says so, then contradicts itself, idea 14). For the most part, GOGC and GOMEMLIMIT are set as described. Yet the foreword promises to flag significant differences between versions (p. xxviii), and two are missing. It is based "mainly on Go 1.26 and later versions" (my translation, p. xxviii). Only one page says: "This book is based on Go 1.24" (my translation, p. 467). It makes an exception for testing/synctest, the testing package that simulates the clock, stabilized in Go 1.25.
- Go 1.24: maps use Swiss Tables (idea 11). Buckets and the 6.5 factor belong to history.
- Go 1.25: GOMAXPROCS reads the cgroup CPU quota, if the
goline ofgo.modsays 1.25 or more (idea 1).
Two other points predate this base. The first is wrong, the second only qualified:
- Go 1.16: on Linux, the runtime returns unused memory to the system right away (
MADV_DONTNEED), not lazily (MADV_FREE) as the book writes (p. 107). In my test, the process keeps 3 MB after returning its memory, against 207 MB with the old behavior (GODEBUG=madvdontneed=0). - Go 1.19: a Go program raises by itself the limit on open files that the system imposes on it. The book's note about a ceiling of 1024 open files (p. 292) stays true for the system, but no longer for a Go program: my test opens 5000 at once.
What the book gets right on recent versions: atomic types since Go 1.19, atomic And and Or since Go 1.23 (a lock-free bitwise AND or OR), and panic(nil). Since Go 1.21, recover then returns a *runtime.PanicNilError error instead of nil (runtime source code).
Who is it for?
Read it if
- you have written Go in production for several months and want to understand what the runtime does with your memory and goroutines.
- you tune a service in a container: GC, memory, processor.
- you like checking: you will run a
docker run golang:1.26to test a claim before believing it. - you read English terms without trouble: the book translates neither scheduler nor runtime, and points to a glossary at the end (p. xxvii).
- you want a map of the runtime before reading its sources, and you accept correcting it along the way.
Skip it if
- you are new to Go: the book itself says it is not "an introductory tutorial to Go" (my translation, p. xxvii). Start with a course or an introductory book.
- you want code to copy as it is: it is not "a catalog of turnkey solutions" either (my translation, p. xxviii). It explains mechanisms, and you replay the code.
- you want the exact behavior of Go 1.26 without cross-checking: several descriptions date from Go 1.23.
Going further
- The Learning Go note: the language, before the engine.
- The System Programming Essentials with Go note: the system under the language, as a complement.
- The course Slices and maps: the types of ideas 9 and 11, usage side.
- The course Goroutines and channels: to try out ideas 14 and 17 with examples.
- The course Functions and errors:
defer,panicandrecover, usage side. - The course Advanced concurrency: mutex, atomics and channels, to extend ideas 17 and 18.
Note based on: the D-BookeR PDF, provided by the publisher. Twenty chapters read in full (2, 3, 8 to 21, 23 to 26). Parts read of chapters 1, 4, 5, 6, 7, 22 and 27, and of a few appendices. The "My reading" passages are mine: tests under several Go versions, and official Go sources.
Comments (0)